dumpspedia logo
a requirement to achieve service discovery and load balancing across clusters with Cluster Mesh?
Each cluster must be in the same geographical location.
All clusters must run the same distribution and version of Kubernetes.
All clusters must run the same version of Cilium.
Each cluster must be configured with a unique cluster ID.
Technical explanation
Every cluster participating in a Cilium Cluster Mesh must have a unique cluster name and numeric cluster ID. The numeric ID becomes part of Cluster Mesh security identities and allows Cilium to distinguish identities originating in different clusters. Reusing an ID would create ambiguity in endpoint identity, policy enforcement, and synchronized service information. Current documentation permits IDs from 1 through 255 under the default scaling configuration.
Geographical colocation is not required. Cluster Mesh is specifically designed to extend connectivity, policy, service discovery, and load balancing across clusters that may reside in different regions, clouds, or premises, provided the documented network-connectivity requirements are satisfied. The clusters also do not need to use an identical Kubernetes distribution or exact Kubernetes version.
Option C is unnecessarily strict. Current Cilium documentation permits connected clusters to differ by no more than one minor Cilium release; exact version equality is not mandatory. Other prerequisites include unique and non-conflicting PodCIDRs, compatible datapath modes, node connectivity, and appropriate inter-cluster communication.
The supplied bank incorrectly marks A. The verified answer is D.
Official references
Setting up Cluster Mesh .
Study Guide topic: Cluster Mesh.
What is true about WireGuard encryption on Cilium?
Packets are encrypted when they are destined to the same node from which they were sent. This is to ensure confidentiality of traffic within the node.
It provides encryption for node-to-node, pod-to-node, node-to-pod, and pop-to-pod traffic as long as the pods are on different nodes.
When running in the tunneling mode, pod-to-pod traffic will be sent over the WireGuard tunnel before being transmitted over the overlay tunnel.
When WireGuard is enabled in Cilium, each pod will establish a secure WireGuard tunnel between it and all other known pods in the cluster.
Technical explanation
B is the best answer, with two qualifications. First, “pop-to-pod” is evidently a source typo for “pod-to-pod.” Second, default WireGuard mode encrypts traffic between Cilium-managed pods on different nodes; node-to-node, pod-to-node, and node-to-pod coverage requires enabling the additional encryption.nodeEncryption=true mode.
Cilium creates WireGuard peers per node, not per pod. Each Cilium agent generates a node key pair, advertises the public key through its CiliumNode resource, and forms secure tunnels with other known nodes. This makes D incorrect. Same-node packets do not traverse a WireGuard tunnel because encryption cannot protect them from an observer already able to inspect raw traffic on that host, so A reverses the documented behavior.
C also reverses the encapsulation sequence. In tunnel-routing mode, pod traffic is first encapsulated for the VXLAN or Geneve overlay and is then encapsulated by WireGuard. The result is double encapsulation, with WireGuard protecting the overlay packet while it crosses the network between nodes.
Thus, B describes WireGuard’s supported traffic coverage most closely, but exam candidates should remember the separate node-encryption configuration requirement.
Official references
WireGuard Transparent Encryption
Study Guide topic: WireGuard peer architecture, encrypted traffic matrix, same-node behavior, and encapsulation order.
What is correct about the Kubernetes Host Scope IP Address Management (IPAM) mode?
It supports multiple CIDRs (Classless Inter-Domain Routing) per cluster
It supports multiple CIDRs (Classless Inter-Domain Routing) per node.
It can beset by using the ipam: crd configuration flag.
It supports both tunnel and direct routing modes.
Technical explanation
Kubernetes host-scope IPAM can be used with both Cilium tunnel routing and native direct routing. The IPAM mechanism determines how each node receives and locally allocates pod addresses; it does not inherently require a particular packet-forwarding model. The current IPAM feature matrix explicitly marks both tunnel routing and direct routing as supported for Kubernetes host-scope mode.
In this mode, Kubernetes allocates a PodCIDR to each node and publishes it through the standard v1.Node resource, normally in spec.podCIDR or spec.podCIDRs . The Cilium agent waits for the relevant range and allocates individual pod addresses from that node-specific CIDR. The correct configuration is ipam: kubernetes or the Helm equivalent ipam.mode=kubernetes , not ipam: crd ; therefore, C is false.
The documented feature matrix does not provide multiple CIDRs per cluster or multiple CIDRs per node for this mode, eliminating A and B. Multi-pool IPAM is the Cilium mode designed for allocating per-node CIDRs from multiple configurable pools.
Because Kubernetes host-scope IPAM supports either overlay tunneling or direct routing while the other statements contradict its capabilities or configuration, D is correct.
Official references
IP Address Management ; Kubernetes Host Scope .
Study Guide topic: Installation and Configuration.
What is the default policy enforcement behavior?
If any rule selects an Endpoint and the rule has an ingress section, the Endpoint goes Into default deny at egress. f any rule selects an Endpoint and the rule has an egress section, the Endpoint goes into default deny at ingress.
If any rule selects an Endpoint and the rule has an ingress section, the Endpoint goes Into default allow at egress, f any rule selects an Endpoint and the rule has an egress section, the Endpoint goes into default allow at ingress.
If any rule selects an Endpoint and the rule has an ingress section, the Endpoint goes Into default allow at Ingress, f any rule selects an Endpoint and the rule has an egress section, the Endpoint goes into default allow at egress.
If any rule selects an Endpoint and the rule has an ingress section, the Endpoint goes into default deny at ingress. f any rule selects an Endpoint and the rule has an egress section, the Endpoint goes into default deny at egress.
Technical explanation
In Cilium’s default policy-enforcement mode, an endpoint initially permits ingress and egress traffic. Enforcement changes independently for each direction when a policy selects that endpoint. If a selecting rule contains an ingress section, the endpoint enters default-deny mode for ingress. If a selecting rule contains an egress section, it enters default-deny mode for egress. Only traffic explicitly permitted by the applicable policy rules remains allowed in the restricted direction.
This per-direction behavior is important. An ingress-only policy does not automatically restrict egress, and an egress-only policy does not automatically restrict ingress. Options A and B reverse the relationship between the rule section and the direction being enforced. Option C incorrectly states that selection places the endpoint into default-allow mode; default allow describes the endpoint’s condition before it is selected by an enforcing policy.
Cilium also supports always and never enforcement modes. In always , enforcement applies even to endpoints not selected by policy. In never , policy enforcement is disabled. Policies can additionally use enableDefaultDeny for specialized visibility configurations, but those controls do not change the normal default behavior described in the question.
Official references
Policy Enforcement Modes .
Study Guide topic: Network Policy.
Which Cilium command should you execute to gather network-related troubleshooting information from your Kubernetes cluster?
cilium bugtool
cilium debuginfo
cilium status --verbose
cilium sysduwp
Technical explanation
The intended answer is D, but the option contains a source-bank typographical error. The valid command is cilium sysdump , not cilium sysduwp . Read literally, none of the four displayed commands exactly answers the question.
The Cilium CLI’s sysdump operation gathers cluster-wide troubleshooting material, including Cilium configuration and endpoint state, agent and operator logs, Kubernetes workload information, routing and interface details, kernel messages, service state, policies, and selected eBPF-map output. This consolidated archive is the preferred diagnostic package when investigating Kubernetes networking or preparing a support report.
cilium status --verbose provides expanded health and deployment status, but it does not collect the comprehensive diagnostic archive requested. debuginfo is associated with the in-agent debug client—currently documented as cilium-dbg debuginfo —and produces useful local-agent API information; in Kubernetes environments it is already included as part of the system dump. cilium bugtool is not the current cluster-wide Cilium CLI command requested here.
For an exam-ready correction, option D should read cilium sysdump .
Official references
Cilium Troubleshooting and Sysdump
Study Guide topic: Cilium CLI troubleshooting, system dumps, and diagnostic collection.
Which affirmation is true about eBPF host-routing?
eBPF host-routing ensures that traffic is distributed evenly across multiple backend services, improving the overall efficiency of load balancing.
eBPF host-routing allows the network stack to prepare larger GSO (transmit) and GRO (receive) packets to reduce the number of times the stack is traversed, which improves performance and latency.
eBPF host-routing allows bypassing iptables and upper stack overhead in the host namespace and some context-switching overhead when traversing through the Virtual Ethernet pairs.
eBPF host-routing is particularly suitable when pods are exposed behind Kubernetes Services, which face external clients from the Internet.
Technical explanation
C accurately describes eBPF host-routing. In a conventional datapath, packets may traverse substantial portions of the host networking stack and its iptables hooks even when Cilium performs routing decisions with eBPF. eBPF host-routing takes a more direct datapath, bypassing iptables and the upper host stack while providing a faster transition between the host and pod network namespaces. This reduces processing and context-switching overhead and can improve throughput and latency.
Option A describes load-balancing behavior rather than host routing. Backend distribution is implemented through Cilium’s service load-balancer maps and algorithms. Host routing can improve the path used by resulting packets, but it does not itself guarantee even backend selection.
Option B is the description of BIG TCP. BIG TCP increases the size of internal GSO and GRO packets to reduce stack traversal. Although BIG TCP requires eBPF host-routing in supported Cilium configurations, the two are distinct features.
Option D is overly specific and does not define the feature. Host routing optimizes compatible pod traffic generally, subject to kernel, kube-proxy-replacement, masquerading, netfilter, encryption, and integration constraints.
Official references
Cilium eBPF Host-Routing
Study Guide topic: eBPF host-routing, host-stack bypass, veth traversal, and performance.
You are tasked to install Cilium and enable transparent encryption in a cluster in which the following conditions applies:
� Internal cluster traffic is IPv6-only
� The current cluster is running on 5001 nodes
� The cluster is planned to connect to another cluster which has 5001 nodes through Cluster Mesh
What are your recommendations regarding transparent encryption?
Enable the wireguard transparent encryption.
Enable the IPSec transparent encryption.
Clusters have too many nodes for transparent encryption.
Transparent encryption requires an IPv4-only network.
Technical explanation
A is a supported recommendation: Cilium’s WireGuard implementation provides transparent encryption between Cilium-managed endpoints, works with Cluster Mesh, and distributes node public keys to remote clusters through clustermesh-apiserver . All participating clusters must enable WireGuard, and inter-cluster firewalls must permit UDP port 51871. IPv6-only pod traffic does not inherently disqualify WireGuard.
However, this question is no longer uniquely answerable from current Cilium documentation. Current IPsec documentation supports IPv6 pod-to-pod connectivity and sets its cluster or Cluster Mesh limit at more than 65,535 nodes. The described mesh contains 10,002 nodes, so option B is also technically supportable under the stated facts. The older distinction apparently assumed by the supplied key is no longer sufficient to exclude IPsec.
Options C and D are definitively false. Ten thousand and two nodes remain below the documented IPsec ceiling, and transparent encryption is not restricted to IPv4. WireGuard may still be selected for its automatic per-node key-pair distribution and simpler Cluster Mesh integration, but workload performance, kernel support, firewall rules, key-management requirements, and operational testing should inform a production recommendation.
Official references
WireGuard Transparent Encryption , IPsec Transparent Encryption
Study Guide topic: Transparent-encryption selection, IPv6, Cluster Mesh, and scaling limits.
If you are required to block ingress traffic from external IPs for all pods in your cluster, which of the following network policies would be the best fit?
CiliumNetworkPolicy
CiliumGlobalPolicy
NetworkPolicy
CiliumClusterWideNetworkPolicy
Technical explanation
A cluster-wide requirement is best implemented with CiliumClusterwideNetworkPolicy , whose correct resource spelling is CiliumClusterwideNetworkPolicy . Unlike a namespaced CiliumNetworkPolicy , this Cilium CRD is non-namespaced and can select endpoints across the entire cluster.
To deny external ingress for every Cilium-managed pod, a cluster-wide policy can use an empty endpointSelector and an ingressDeny rule selecting the world entity. Cilium defines world as network endpoints outside the cluster. An alternative allow-list construction can permit only the cluster entity, thereby excluding external sources, but an explicit deny rule usually communicates the requirement more directly.
A standard Kubernetes NetworkPolicy and a CiliumNetworkPolicy are namespaced, requiring repeated resources in every applicable namespace. CiliumGlobalPolicy is not a valid Cilium resource type. Although the option capitalizes “Wide” differently from the actual kind, D unmistakably identifies the intended cluster-scoped policy.
Official references
Cilium Deny Policies , Cilium Network Policy Types
Study Guide topic: Cluster-scoped policies, external traffic, and reserved entities.
What is true about Layer 7 protocol visibility in Cilium?
DNS visibility in available in the ingress direction only.
It can be enabled by deploying a standard Kubernetes network policy.
It results in traffic being proxied through an Envoy instance.
It supports any Layer 7 protocols, including SSH, Telnet and FTP.
Technical explanation
Layer 7 protocol visibility redirects traffic matching the relevant L7 rules to Cilium’s node-local proxy, which is Envoy. Envoy parses supported application protocols and supplies the resulting request or response metadata to Cilium’s observability pipeline. Therefore, C correctly identifies the architectural consequence of enabling this visibility.
The feature requires L7 proxy support and an appropriate CiliumNetworkPolicy containing Layer 7 rules. A standard Kubernetes NetworkPolicy is limited to Layer 3 and Layer 4 concepts and cannot express Cilium’s HTTP, DNS, or generic application-protocol rules, so B is incorrect.
A is also incorrect. DNS policy and visibility are commonly applied to pod egress queries, and Cilium’s model is not restricted to ingress-only DNS visibility. D overstates protocol coverage. Cilium supports defined L7 parsers and policy types—most prominently HTTP, DNS, Kafka, and supported generic Envoy-based protocols—but it does not promise arbitrary visibility for every application protocol. SSH, Telnet, and FTP cannot simply be assumed to receive native semantic parsing.
An operational caveat is that L7 visibility rules also affect policy enforcement: they are not merely passive packet logging instructions.
Official references
Layer 7 Protocol Visibility , Cilium Envoy
Study Guide topic: L7 proxy redirection, CiliumNetworkPolicy, protocol parsing, and Hubble visibility.
Which statement is true about Mutual Authentication with Cilium?
By default, data of SPIRE is stored In memory.
Cilium's Mutual authentication has been validated with SPIFFE, the production-ready implementation of SPIRE.
Enabling Mutual Authentication on Cilium requires installing, managing, and configuring a SPIRE server.
Through SPIRE, TLS certificates are automatically managed and frequently rotated.
Technical explanation
SPIRE supplies workload identities as SPIFFE Verifiable Identity Documents, including X.509 key material used for mutual authentication. SPIFFE’s identity model supports automatic issuance, rotation, and revocation, allowing short-lived certificates to be renewed without manually distributing static credentials. This makes D the correct statement.
Option A reverses the documented default. Cilium’s default SPIRE installation requires persistent-volume support. In-memory storage can be selected for laboratory environments by disabling server data storage, but that setting causes SPIRE data to be recreated if the server pod restarts. Option B also reverses the relationship between the projects: SPIFFE defines the identity standards and APIs, while SPIRE is a production-ready implementation of SPIFFE. Cilium’s mutual-authentication integration has been validated with SPIRE.
Option C overstates the operational requirement. A SPIRE server is involved, but Cilium’s Helm chart can deploy and configure the supported SPIRE server and per-node agents. Administrators may provide their own deployment, yet a completely manual installation is not mandatory.
Current documentation classifies this mutual-authentication implementation as beta and notes limitations, including incompatibility with Cluster Mesh trust domains. Those maturity constraints do not change the certificate-management behavior described in D.
Official references
Cilium Mutual Authentication .
Study Guide topic: Service Mesh.
Which command is used to enable logging at the debug log level of Cilium agents7
cilium log level --set=debug
cilium logging.level=debug
cilium config set debug true
cilium logging debug
Technical explanation
cilium config set debug true follows the supported Cilium CLI configuration syntax and sets the debug configuration key to true . The cilium config set command accepts a key/value pair and, by default, restarts the Cilium pods so that the changed configuration is applied. The Cilium configuration documentation defines debug as the setting that enables full debug mode. This increases agent logging verbosity and causes eBPF programs to emit additional visibility events for diagnostic use.
Options A, B, and D do not match documented Cilium CLI command structures. There is no cilium log level --set=debug command in the Cilium CLI hierarchy, and neither cilium logging.level=debug nor cilium logging debug is valid configuration syntax. A Helm-managed installation may also enable debugging through the chart value debug.enabled=true , but that does not make any of the alternative commands correct.
Debug mode should be enabled deliberately because it increases log volume and may generate additional datapath visibility information. After troubleshooting, operators should normally restore the previous setting to avoid unnecessary operational overhead.
The supplied answer key incorrectly identifies B. The verified answer is C.
Official references
Cilium configuration ; Cilium CLI `config set` ; Helm values .
Study Guide topic: Installation and Configuration.
How does Cilium primarily improve security in Kubernetes clusters?
By using API Gateway configurations.
By securing and encrypting database data.
By providing backup solutions for persistent volumes.
By implementing network policies at multiple OSI model layers.
Technical explanation
Cilium primarily improves Kubernetes network security through identity-aware policy enforcement across Layers 3 through 7. Standard Kubernetes NetworkPolicy resources provide Layer 3 and Layer 4 controls, while CiliumNetworkPolicy extends enforcement to application-layer rules. Policies can select workloads by labels and identity, restrict protocols and destination ports, control communication with CIDRs or entities, apply DNS/FQDN rules, and authorize supported HTTP or gRPC operations. This multi-layer enforcement is the capability described by D.
API Gateway and Gateway API configurations can contribute to controlling north-south traffic, but they are not Cilium’s primary or comprehensive security mechanism. Database encryption is implemented by database, storage, or encryption-management systems rather than being a general function of Cilium. Persistent-volume backup is similarly outside Cilium’s CNI, network-policy, and observability responsibilities.
Cilium’s identity model is especially important in dynamic Kubernetes environments. Security policy follows workload identities derived from labels instead of depending exclusively on changing pod IP addresses. At Layer 7, traffic is redirected to Envoy when protocol-aware inspection or enforcement is required, while eBPF supplies the efficient kernel datapath for lower-layer processing.
Official references
Introduction to Cilium and Hubble ; Network Policy ; Layer 7 Policies .
Study Guide topic: Network Policy.
What is correct about this Cilium Network Policy?
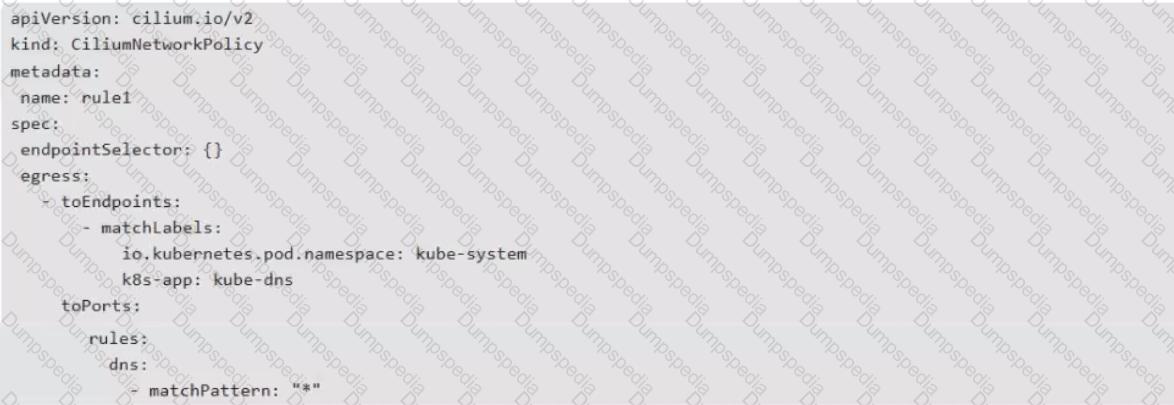
Question 21 Cilium Network Policy exhibit
It will allow all traffic to the Kubemetes DNS servers from any pod in the default namespace.
It will allow all traffic to the Kubernetes DNS servers from any pod across all namespaces in the cluster
It will deny all traffic to the Kubernetes DNS servers from any pod across all namespaces in the cluster.
It will deny all traffic to the Kubernetes DNS servers from any pod in the default namespace.
Technical explanation
The intended policy selects every Cilium-managed endpoint in the namespace where the CiliumNetworkPolicy is created because endpointSelector: {} is empty. The manifest does not specify metadata.namespace ; if it is applied normally in the default namespace, the selected endpoints are therefore all pods in default , not pods across every namespace. The egress destination selector identifies pods in kube-system carrying k8s-app: kube-dns , while matchPattern: "*" allows all DNS query names handled by the DNS rule. This supports the intended answer A.
There is, however, a material defect in the exhibit: toPorts is a list in the Cilium policy schema, but the image shows rules directly beneath toPorts without a preceding list marker. The official form is toPorts: , followed by - ports: and rules: within that list item. Port 53 and its protocol should also be stated explicitly. Exactly as displayed, the manifest should not be treated as a valid deployable policy.
The question should be corrected before examination use. Once the missing list item and port definition are restored, A accurately describes its scope and effect.
Official references
Using Kubernetes Constructs in Policy ; Layer 7 Protocol Visibility .
Study Guide topic: Network Policy.
What are the differences between Ingress and Gateway API?
Ingress and Gateway API serve the same purpose, but they are Just different names for the same Kubernetes resource. Ingress is used in older Kubernetes versions, while Gateway API is the updated version for modern clusters, but the underlying functionality is identical.
Ingress primarily targets exposing HTTP applications with a simple, declarative syntax. Gateway API exposes a more general API for proxying that can be used for more protocols than just HTTP, and models more infrastructure components to provide better deployment and management options for cluster operators.
Cilium offers seamless integration with the Gateway API, enhancing Kubernetes networking and security through advanced features powered by eBPF. This integration provides a robust solution for network management. In contrast, Ingress relies on IPtables for its functionality.
Gateway API is primarily used for internal cluster routing, while Ingress is exclusively for external traffic management. Gateway API does not support routing for internet-exposed services, whereas Ingress is specifically designed for that purpose.
Technical explanation
Ingress provides a comparatively simple API for exposing HTTP and HTTPS applications through host- and path-based routing. Gateway API is a broader, extensible family of resources that separates infrastructure configuration from application routing. Resources such as GatewayClass , Gateway , HTTPRoute , GRPCRoute , TLSRoute , TCPRoute , and UDPRoute model listeners, routes, protocols, ownership, and attachment relationships explicitly.
Gateway API was designed around operational roles. An infrastructure provider can manage the GatewayClass , a cluster operator can provision a Gateway , and an application team can own a route attached to that Gateway. This offers clearer delegation than the single Ingress resource and supports protocols and traffic-management functions beyond the original Ingress model.
The two APIs are not simply different names for identical functionality, so A is false. Option C is also inaccurate because Cilium’s implementations of both Ingress and Gateway API integrate with its eBPF datapath and Envoy; Ingress is not inherently an iptables-only implementation. Option D incorrectly limits Gateway API to internal routing. It can expose internet-facing applications through generated LoadBalancer or NodePort Services or through host-network listeners.
Official references
Migrating from Ingress to Gateway ; Gateway API Support .
Study Guide topic: Service Mesh.
When considering changing an existing cluster's IPAM (IP address management) mode, what is the safest path?
Update the IPAM mode through Kubernetes Node resource.
Change the IPAM mode and restart the Cilium Agents.
Directly modify the IPAM configuration of the existing cluster.
Install a fresh Kubernetes cluster with a new IPAM configuration.
Technical explanation
The official IPAM documentation expressly states that the safest way to change IPAM mode is to install a fresh Kubernetes cluster using the required new IPAM configuration. A live cluster already contains allocated workload addresses, node routing state, Cilium endpoint state, service state, and potentially cloud-provider resources that depend on the active allocator. Replacing the allocator in place can invalidate these assumptions and cause persistent connectivity disruption rather than merely a short agent restart.
Updating a Kubernetes Node object does not generally convert Cilium’s IPAM mode. The responsible resource and allocation behavior depend on the selected mode: Kubernetes host-scope IPAM, cluster-pool IPAM, multi-pool IPAM, CRD-backed modes, and cloud-specific allocators manage address information differently. Restarting agents after changing a configuration value likewise does not constitute a safe migration plan, because existing endpoints and routes may retain state created under the former allocator.
Cilium advises against changing the IPAM mode of an existing cluster unless a specifically documented migration procedure applies. The currently documented exception is migration from cluster-pool IPAM to multi-pool IPAM. As the question provides no such constrained scenario, D is the unambiguously safest answer.
Official references
IP Address Management .
Study Guide topic: Installation and Configuration.
TESTED 22 Oct 2026