Pre-Winter Sale - Limited Time 65% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: 65percent

Welcome To DumpsPedia

Databricks-Generative-AI-Engineer-Associate Sample Questions Answers

Questions 4

A Generative Al Engineer is tasked with developing an application that is based on an open source large language model (LLM). They need a foundation LLM with a large context window.

Which model fits this need?

Options:

A.

DistilBERT

B.

MPT-30B

C.

Llama2-70B

D.

DBRX

Buy Now
Questions 5

A Generative Al Engineer has created a RAG application to look up answers to questions about a series of fantasy novels that are being asked on the author’s web forum. The fantasy novel texts are chunked and embedded into a vector store with metadata (page number, chapter number, book title), retrieved with the user’s query, and provided to an LLM for response generation. The Generative AI Engineer used their intuition to pick the chunking strategy and associated configurations but now wants to more methodically choose the best values.

Which TWO strategies should the Generative AI Engineer take to optimize their chunking strategy and parameters? (Choose two.)

Options:

A.

Change embedding models and compare performance.

B.

Add a classifier for user queries that predicts which book will best contain the answer. Use this to filter retrieval.

C.

Choose an appropriate evaluation metric (such as recall or NDCG) and experiment with changes in the chunking strategy, such as splitting chunks by paragraphs or chapters.

Choose the strategy that gives the best performance metric.

D.

Pass known questions and best answers to an LLM and instruct the LLM to provide the best token count. Use a summary statistic (mean, median, etc.) of the best token counts to choose chunk size.

E.

Create an LLM-as-a-judge metric to evaluate how well previous questions are answered by the most appropriate chunk. Optimize the chunking parameters based upon the values of the metric.

Buy Now
Questions 6

A Generative AI Engineer at an automotive company would like to build a question-answering chatbot to help customers answer specific questions about their vehicles. They have:

    A catalog with hundreds of thousands of cars manufactured since the 1960s

    Historical searches with user queries and successful matches

    Descriptions of their own cars in multiple languages

They have already selected an open-source LLM and created a test set of user queries. They need to discard techniques that will not help them build the chatbot. Which do they discard?

Options:

A.

Setting chunk size to match the model ' s context window to maximize coverage

B.

Implementing metadata filtering based on car models and years

C.

Fine-tuning an embedding model on automotive terminology

D.

Adding few-shot examples for response generation

Buy Now
Questions 7

A Generative AI Engineer is developing a patient-facing healthcare-focused chatbot. If the patient’s question is not a medical emergency, the chatbot should solicit more information from the patient to pass to the doctor’s office and suggest a few relevant pre-approved medical articles for reading. If the patient’s question is urgent, direct the patient to calling their local emergency services.

Given the following user input:

“I have been experiencing severe headaches and dizziness for the past two days.”

Which response is most appropriate for the chatbot to generate?

Options:

A.

Here are a few relevant articles for your browsing. Let me know if you have questions after reading them.

B.

Please call your local emergency services.

C.

Headaches can be tough. Hope you feel better soon!

D.

Please provide your age, recent activities, and any other symptoms you have noticed along with your headaches and dizziness.

Buy Now
Questions 8

A Generative AI Engineer is building an interactive catalog for a company’s inventory system that allows users to search for any item using a plain-text description. There are currently about 17,000 items, and new items are not frequently added. They need a solution that will be the most cost-effective and easy for the company to maintain.

Which solution should the engineer choose?

Options:

A.

Storage-optimized vector search with a Direct Vector Access index, triggered sync.

B.

Standard vector search with Databricks-managed embeddings and a Delta Sync index, continuous sync.

C.

Standard vector search with self-managed embeddings and a Delta Sync index, continuous sync.

D.

Standard vector search with Databricks-managed embeddings and a Delta Sync index, triggered sync.

Buy Now
Questions 9

A Generative Al Engineer is ready to deploy an LLM application written using Foundation Model APIs. They want to follow security best practices for production scenarios

Which authentication method should they choose?

Options:

A.

Use an access token belonging to service principals

B.

Use a frequently rotated access token belonging to either a workspace user or a service principal

C.

Use OAuth machine-to-machine authentication

D.

Use an access token belonging to any workspace user

Buy Now
Questions 10

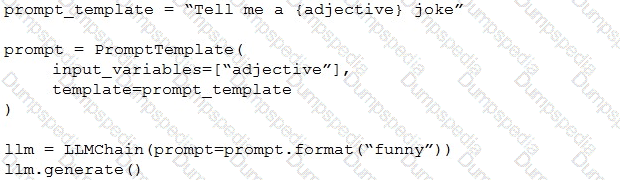
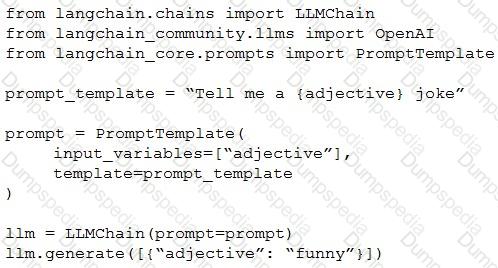
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.
10

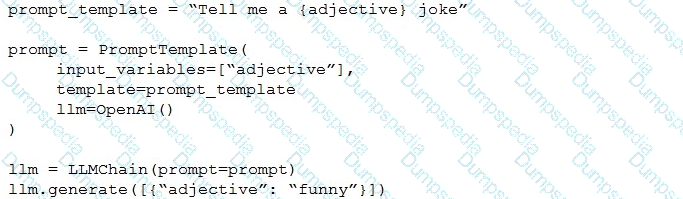
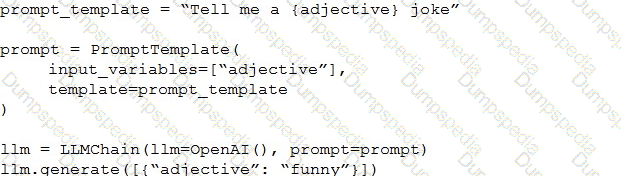
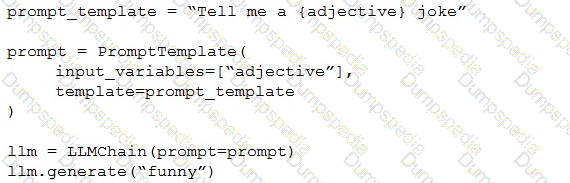
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?

A)
10

B)

10

C)

10

D)

10

Options:

A.

Option A

B.

Option B

C.

Option C

D.

Option D

Buy Now
Questions 11

What is an effective method to preprocess prompts using custom code before sending them to an LLM?

Options:

A.

Directly modify the LLM’s internal architecture to include preprocessing steps

B.

It is better not to introduce custom code to preprocess prompts as the LLM has not been trained with examples of the preprocessed prompts

C.

Rather than preprocessing prompts, it’s more effective to postprocess the LLM outputs to align the outputs to desired outcomes

D.

Write a MLflow PyFunc model that has a separate function to process the prompts

Buy Now
Questions 12

What is the most suitable library for building a multi-step LLM-based workflow?

Options:

A.

Pandas

B.

TensorFlow

C.

PySpark

D.

LangChain

Buy Now
Questions 13

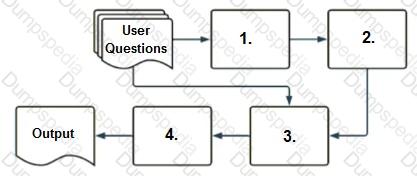
A company has a typical RAG-enabled, customer-facing chatbot on its website.
13

Select the correct sequence of components a user ' s questions will go through before the final output is returned. Use the diagram above for reference.

Options:

A.

1.embedding model, 2.vector search, 3.context-augmented prompt, 4.response-generating LLM

B.

1.context-augmented prompt, 2.vector search, 3.embedding model, 4.response-generating LLM

C.

1.response-generating LLM, 2.vector search, 3.context-augmented prompt, 4.embedding model

D.

1.response-generating LLM, 2.context-augmented prompt, 3.vector search, 4.embedding model

Buy Now
Questions 14

A Generative Al Engineer is building a RAG application that answers questions about internal documents for the company SnoPen AI.

The source documents may contain a significant amount of irrelevant content, such as advertisements, sports news, or entertainment news, or content about other companies.

Which approach is advisable when building a RAG application to achieve this goal of filtering irrelevant information?

Options:

A.

Keep all articles because the RAG application needs to understand non-company content to avoid answering questions about them.

B.

Include in the system prompt that any information it sees will be about SnoPenAI, even if no data filtering is performed.

C.

Include in the system prompt that the application is not supposed to answer any questions unrelated to SnoPen Al.

D.

Consolidate all SnoPen AI related documents into a single chunk in the vector database.

Buy Now
Questions 15

A company selling gourmet mushroom-growing supplies has a script that runs once per day to scrape various social media platforms for posts that mention its name. The scraped text data is loaded into a Delta table each night for a downstream processing task that summarizes each post and its sentiment for internal use. Given the small size of the company, it only receives a couple hundred posts per day.

Which solution best optimizes for cost and ease of implementation?

Options:

A.

Schedule a nightly job to call OpenAI’s batch inference API, save the results, and terminate the cluster.

B.

Schedule a nightly SQL query with ai_query() calling a pay-per-token endpoint.

C.

Schedule a nightly SQL query with ai_query() calling a provisioned-throughput endpoint.

D.

Schedule a nightly job that runs a notebook to download the model locally, process the records, and terminate the cluster.

Buy Now
Questions 16

A team wants to serve a code generation model as an assistant for their software developers. It should support multiple programming languages. Quality is the primary objective.

Which of the Databricks Foundation Model APIs, or models available in the Marketplace, would be the best fit?

Options:

A.

Llama2-70b

B.

BGE-large

C.

MPT-7b

D.

CodeLlama-34B

Buy Now
Questions 17

A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here’s a sample email:
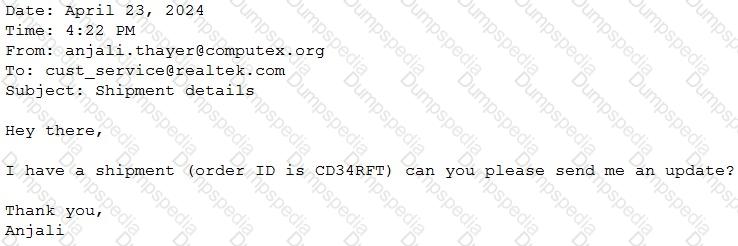
17

They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.

Which prompt will do that?

Options:

A.

You will receive customer emails and need to extract date, sender email, and order ID. You should return the date, sender email, and order ID information in JSON format.

B.

You will receive customer emails and need to extract date, sender email, and order ID. Return the extracted information in JSON format.

Here’s an example: {“date”: “April 16, 2024”, “sender_email”: “sarah.lee925@gmail.com”, “order_id”: “RE987D”}

C.

You will receive customer emails and need to extract date, sender email, and order ID. Return the extracted information in a human-readable format.

D.

You will receive customer emails and need to extract date, sender email, and order ID. Return the extracted information in JSON format.

Buy Now
Questions 18

A Generative AI Engineer needs to allocate costs for an agent deployed via Agent Framework behind AI Gateway. The finance team requires daily reporting by workspace and endpoint, including token usage and request counts. The engineer wants to query this data with SQL and join it to an internal cost-center mapping table.

Which table type best serves their needs?

Options:

A.

AI Gateway usage table.

B.

System Serving, Served Entities table.

C.

Inference Tables.

D.

MLflow experiment run tables.

Buy Now
Questions 19

A Generative AI Engineer at a legal firm is designing a RAG system to analyze historical legal cases. The system needs to process millions of court opinions and legal documents, already organized by time and topic, to track how interpretations of specific laws have evolved over time. All of these documents are in plain-text. The engineer needs to choose a chunking method that would most effectively preserve continuity and the temporal nature of the cases. Which method do they choose?

Options:

A.

Implement windowed summarization with overlapping chunks.

B.

Implement a hierarchical tree structure, like RAPTOR, to group similar legal concepts.

C.

Implement paragraph level embeddings with each chunk.

D.

Implement sentence level embeddings with each chunk tagged with the time to enable metadata filtering.

Buy Now
Questions 20

A Generative AI Engineer is building a compound AI system for an organization. The goal is to automate the processing of incoming customer event reports against a coding system and corporate-guidelines documentation. The system must handle three distinct user-request types: answering questions from guidelines documents, extracting specific event codes from reviewers’ notes, and routing ambiguous requests to the appropriate specialized handler. All three capabilities must operate under a single entry point that interprets user intent and delegates accordingly.

Which Agent Brick should serve as the top-level orchestrator in this architecture?

Options:

A.

Multi-Agent Supervisor, because it can be used without Knowledge Assistant and Information Extraction agents.

B.

Knowledge Assistant, because the chatbot interface can handle multi-turn conversations.

C.

Knowledge Assistant, because it can be configured with multiple vector indexes to handle all three request types simultaneously.

D.

Multi-Agent Supervisor, because it interprets incoming requests and delegates tasks to specialized sub-agents.

Buy Now
Questions 21

Which indicator should be considered to evaluate the safety of the LLM outputs when qualitatively assessing LLM responses for a translation use case?

Options:

A.

The ability to generate responses in code

B.

The similarity to the previous language

C.

The latency of the response and the length of text generated

D.

The accuracy and relevance of the responses

Buy Now
Questions 22

A Generative Al Engineer is setting up a Databricks Vector Search that will lookup news articles by topic within 10 days of the date specified An example query might be " Tell me about monster truck news around January 5th 1992 " . They want to do this with the least amount of effort.

How can they set up their Vector Search index to support this use case?

Options:

A.

Split articles by 10 day blocks and return the block closest to the query.

B.

Include metadata columns for article date and topic to support metadata filtering.

C.

pass the query directly to the vector search index and return the best articles.

D.

Create separate indexes by topic and add a classifier model to appropriately pick the best index.

Buy Now
Questions 23

A Generative AI Engineer is creating an agent-based LLM system for their favorite monster truck team. The system can answer text based questions about the monster truck team, lookup event dates via an API call, or query tables on the team’s latest standings.

How could the Generative AI Engineer best design these capabilities into their system?

Options:

A.

Ingest PDF documents about the monster truck team into a vector store and query it in a RAG architecture.

B.

Write a system prompt for the agent listing available tools and bundle it into an agent system that runs a number of calls to solve a query.

C.

Instruct the LLM to respond with “RAG”, “API”, or “TABLE” depending on the query, then use text parsing and conditional statements to resolve the query.

D.

Build a system prompt with all possible event dates and table information in the system prompt. Use a RAG architecture to lookup generic text questions and otherwise leverage the information in the system prompt.

Buy Now
Questions 24

A Generative Al Engineer is tasked with developing a RAG application that will help a small internal group of experts at their company answer specific questions, augmented by an internal knowledge base. They want the best possible quality in the answers, and neither latency nor throughput is a huge concern given that the user group is small and they’re willing to wait for the best answer. The topics are sensitive in nature and the data is highly confidential and so, due to regulatory requirements, none of the information is allowed to be transmitted to third parties.

Which model meets all the Generative Al Engineer’s needs in this situation?

Options:

A.

Dolly 1.5B

B.

OpenAI GPT-4

C.

BGE-large

D.

Llama2-70B

Buy Now
Questions 25

A Generative AI Engineer is building a Generative AI system that suggests the best matched employee team member to newly scoped projects. The team member is selected from a very large team. The match should be based upon project date availability and how well their employee profile matches the project scope. Both the employee profile and project scope are unstructured text.

How should the Generative Al Engineer architect their system?

Options:

A.

Create a tool for finding available team members given project dates. Embed all project scopes into a vector store, perform a retrieval using team member profiles to find the best team member.

B.

Create a tool for finding team member availability given project dates, and another tool that uses an LLM to extract keywords from project scopes. Iterate through available team members’ profiles and perform keyword matching to find the best available team member.

C.

Create a tool to find available team members given project dates. Create a second tool that can calculate a similarity score for a combination of team member profile and the project scope. Iterate through the team members and rank by best score to select a team member.

D.

Create a tool for finding available team members given project dates. Embed team profiles into a vector store and use the project scope and filtering to perform retrieval to find the available best matched team members.

Buy Now
Questions 26

Generative AI Engineer at an electronics company just deployed a RAG application for customers to ask questions about products that the company carries. However, they received feedback that the RAG response often returns information about an irrelevant product.

What can the engineer do to improve the relevance of the RAG’s response?

Options:

A.

Assess the quality of the retrieved context

B.

Implement caching for frequently asked questions

C.

Use a different LLM to improve the generated response

D.

Use a different semantic similarity search algorithm

Buy Now
Questions 27

A Generative AI Engineer is integrating Mosaic AI Vector Search into a Retrieval-Augmented Generation (RAG) system. The source data, comprising simple text entries, is stored in a Delta table. To simplify the workflow, the engineer plans to use an embedding model served via a Mosaic AI Model Serving endpoint to automatically compute embeddings during data synchronization from the Delta table to the vector search index.

Which method should the engineer use to achieve this integration?
Options:

A.

Delta Sync index with self-managed embeddings.

B.

Direct Vector Access index.

C.

Hybrid embedding computing.

D.

Delta Sync index with managed embeddings.

Buy Now
Exam Code: Databricks-Generative-AI-Engineer-Associate
Exam Name: Databricks Certified Generative AI Engineer Associate
Last Update: Oct 14, 2026
Questions: 90

PDF + Testing Engine

$59.99 $171.4

Testing Engine

$44.99 $128.55

PDF (Q&A)

$49.99 $142.82